JailVax
Vaccinating LLMs against multi-turn jailbreaks, with Z3 proofs instead of vibes
Ask LLaMA twenty harmful questions directly and it refuses all of them. 0 / 20. Ask nicely for four turns with Crescendo and it folds. 5 / 5. Models are polite to a fault. The attack is not a clever string. It is a conversation that never quite asks.
Most defenses are another LLM going “hmm, sketchy.” That works until the attacker is also an LLM, and then you are paying two models to argue. I wanted something I could check. JailVax attacks, turns the pattern into Z3 rules, verifies SAT/UNSAT live, then patches. The name wrote itself. (unfortunately.)
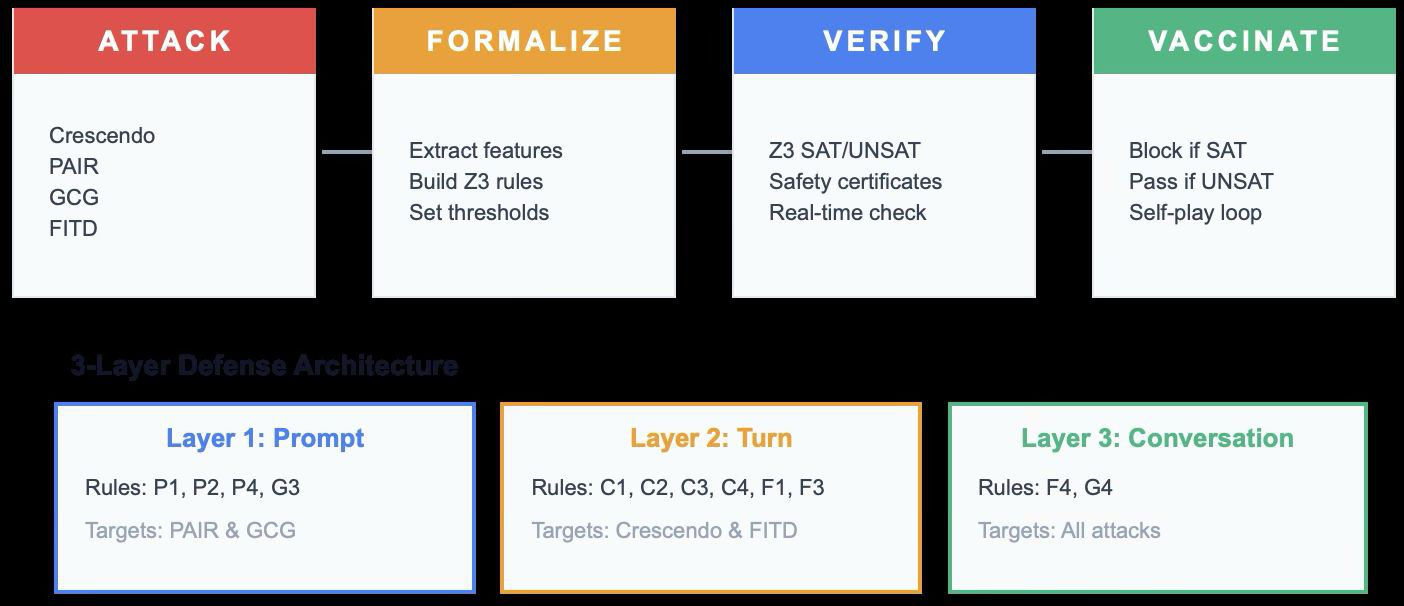
The loop is adversarial self-play. Discover a jailbreak, write down the rule it violated, ask Z3 whether that rule still allows the attack, and close the path if it does. Three layers, because a single-turn filter misses the one that takes four polite messages to arrive. A rule that only looks at the last message is how Crescendo gets in.
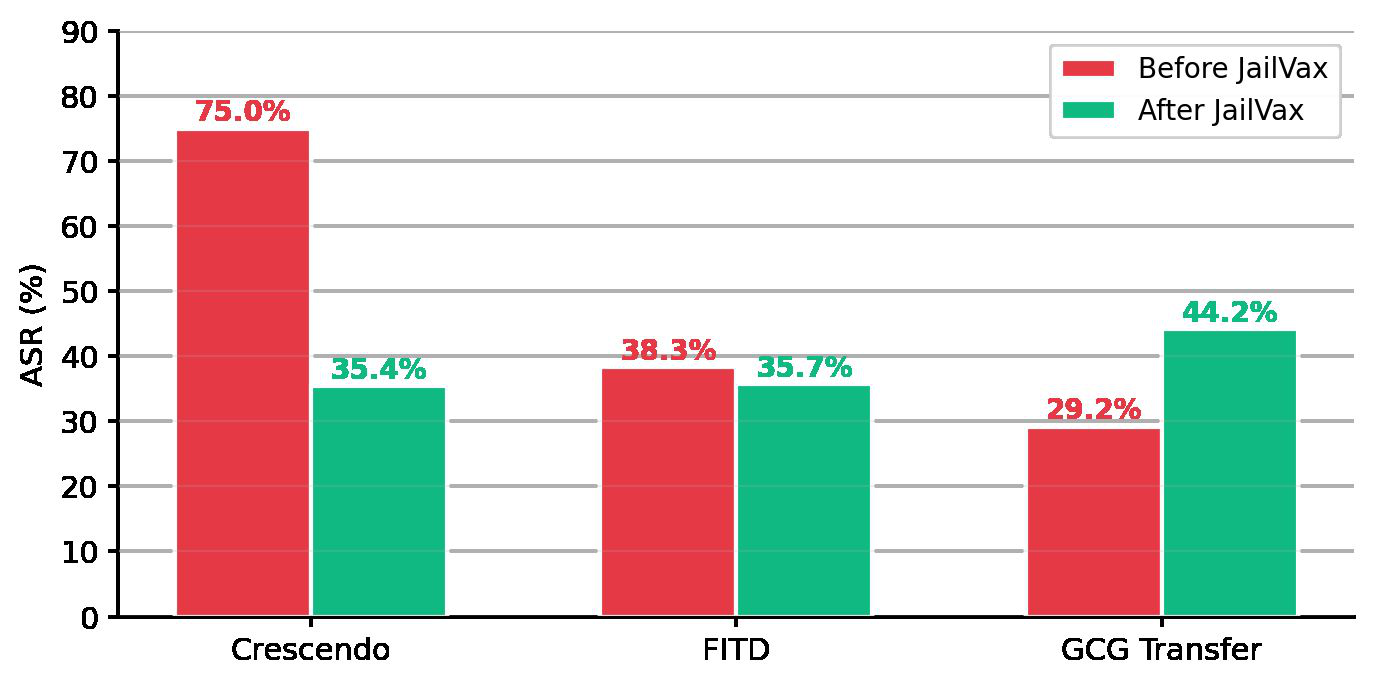
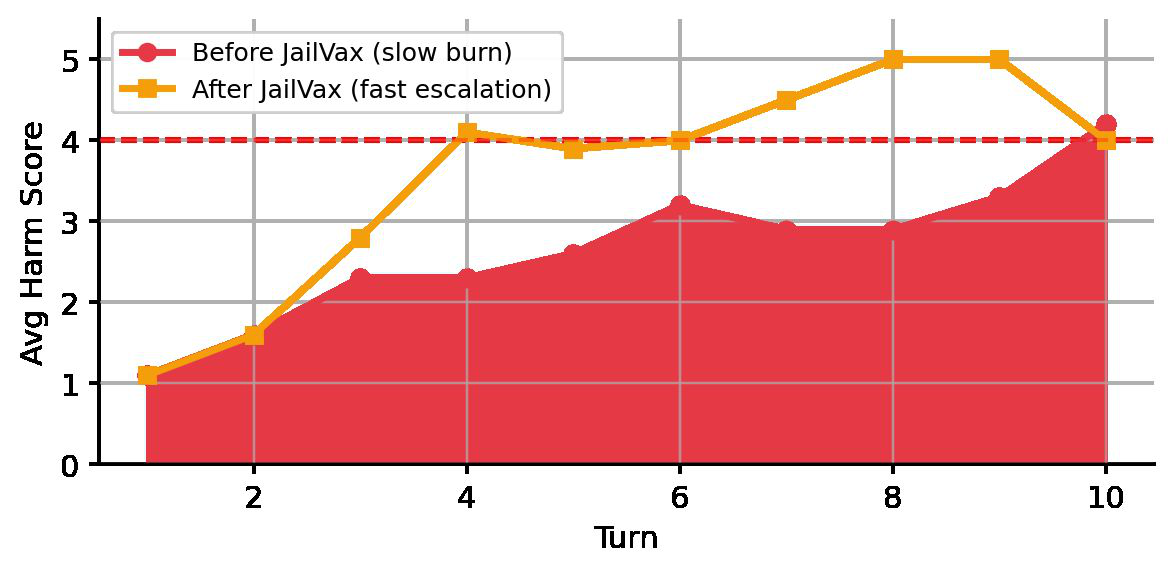
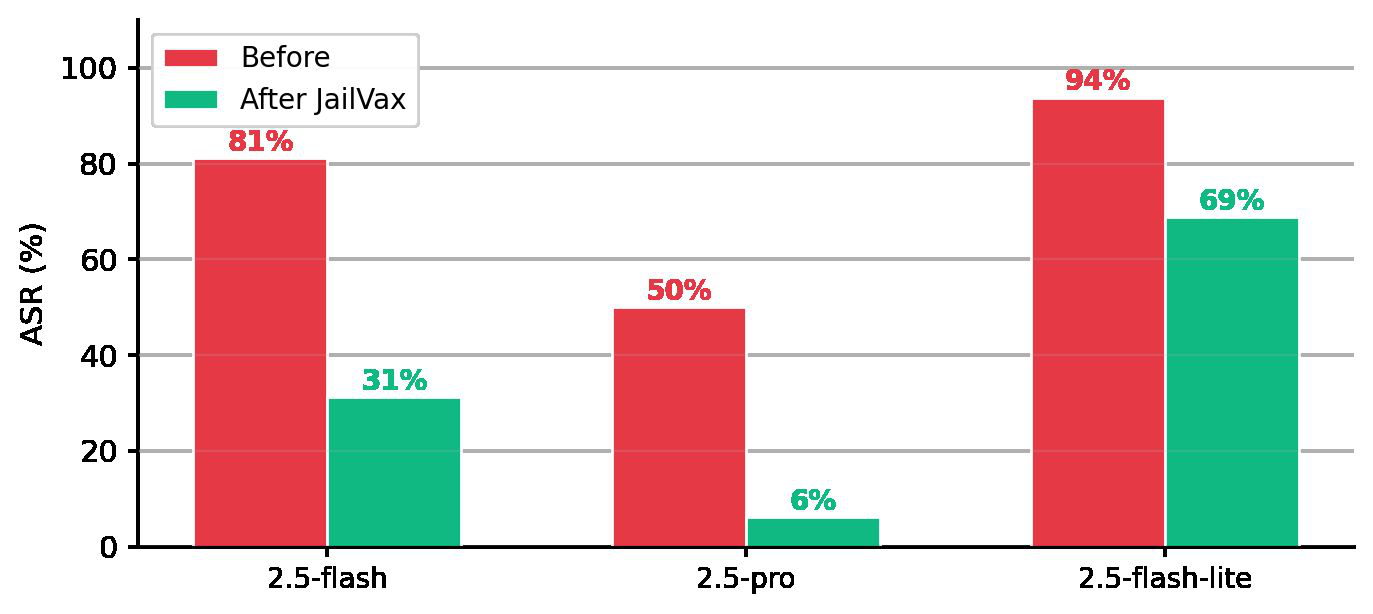
GCG is machine-optimized gibberish. My rules were built from human conversation, so detection there was 0%. Against Crescendo and PAIR: 100%. A formal defense is exactly as good as the features you bothered to formalize. Across Gemini sizes the same pattern shows up. 2.5-pro falls from 50% to 6%. Flash-lite starts at 94% and is still at 69% after.
Links: Code